Rails Survey 2026 - A Land of Bots and Seniors?
The results of the 2026 Ruby on Rails Community Survey were published recently. The results overwhelmingly reflect a core developer population that remains committed to the Rails platform, with significant adoption of AI tools. But we are still sailing on a very leaky boat, with fewer juniors, and an aging senior cohort.
This is all despite the latest DHH controversy when he called an end to coding by hand at Rails World 2026 of course!
When I look back and compare with the 2024 Rails Survey, it is startling how fast things are changing. Just considering the demographics:
- 13+ years experience: up from 30% to 48%
- Under 10 years experience: shrunk from 48% to 32%
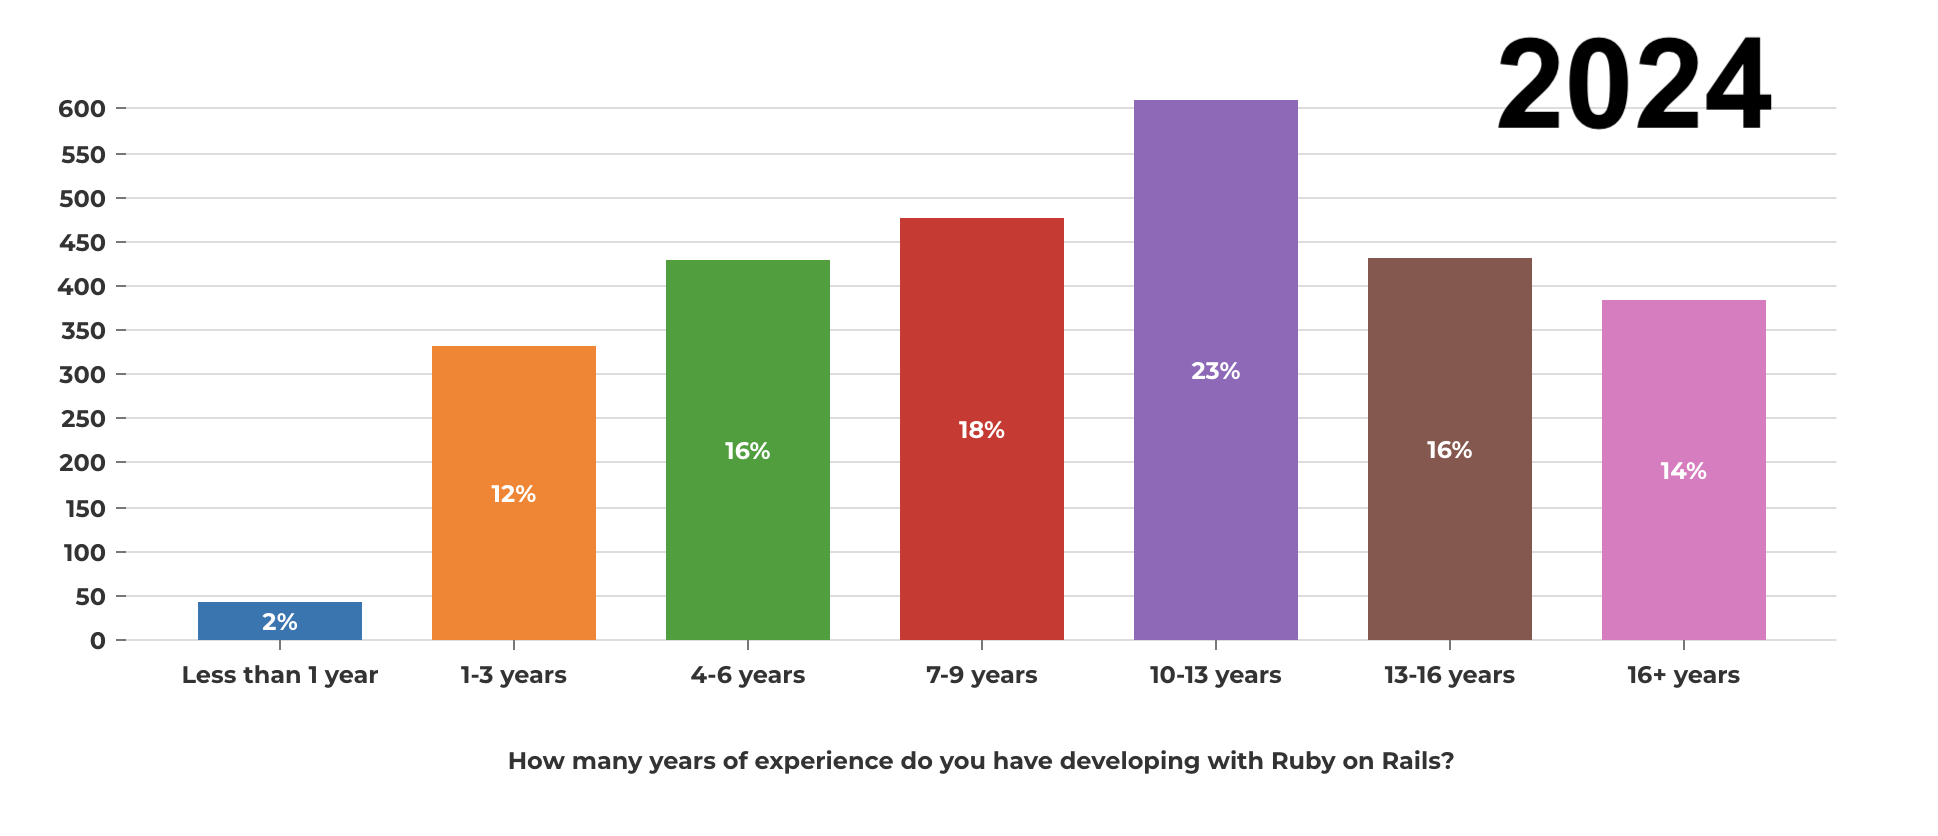
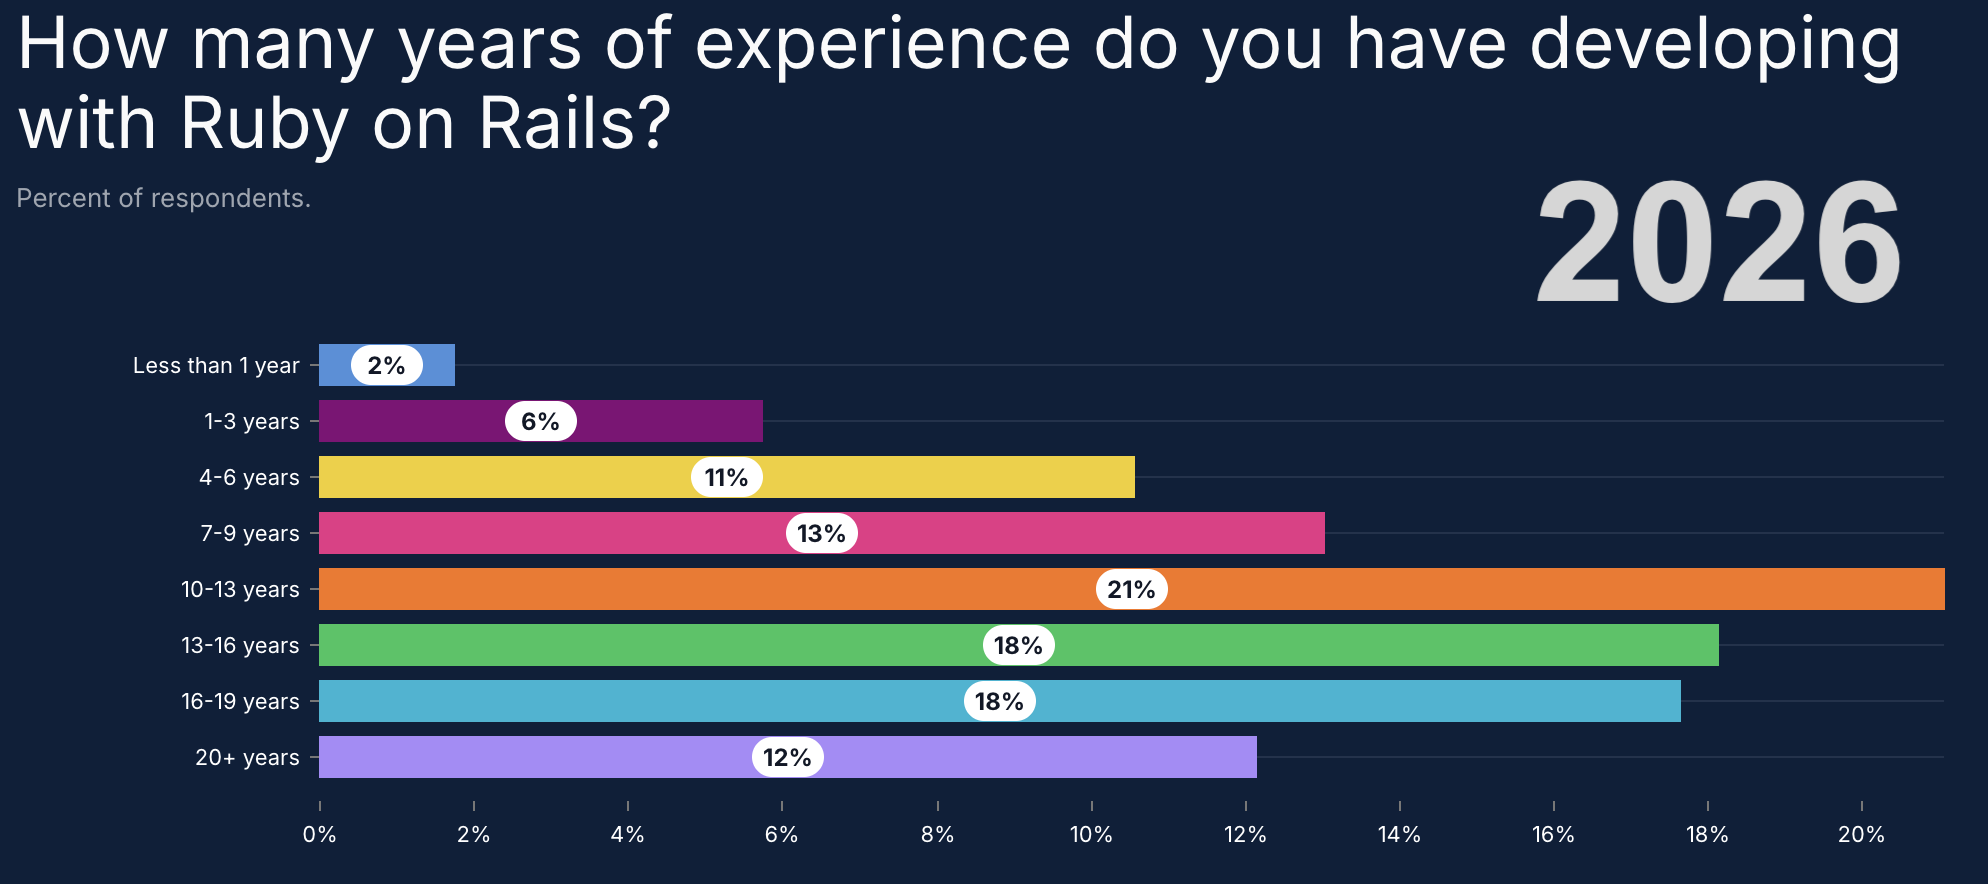
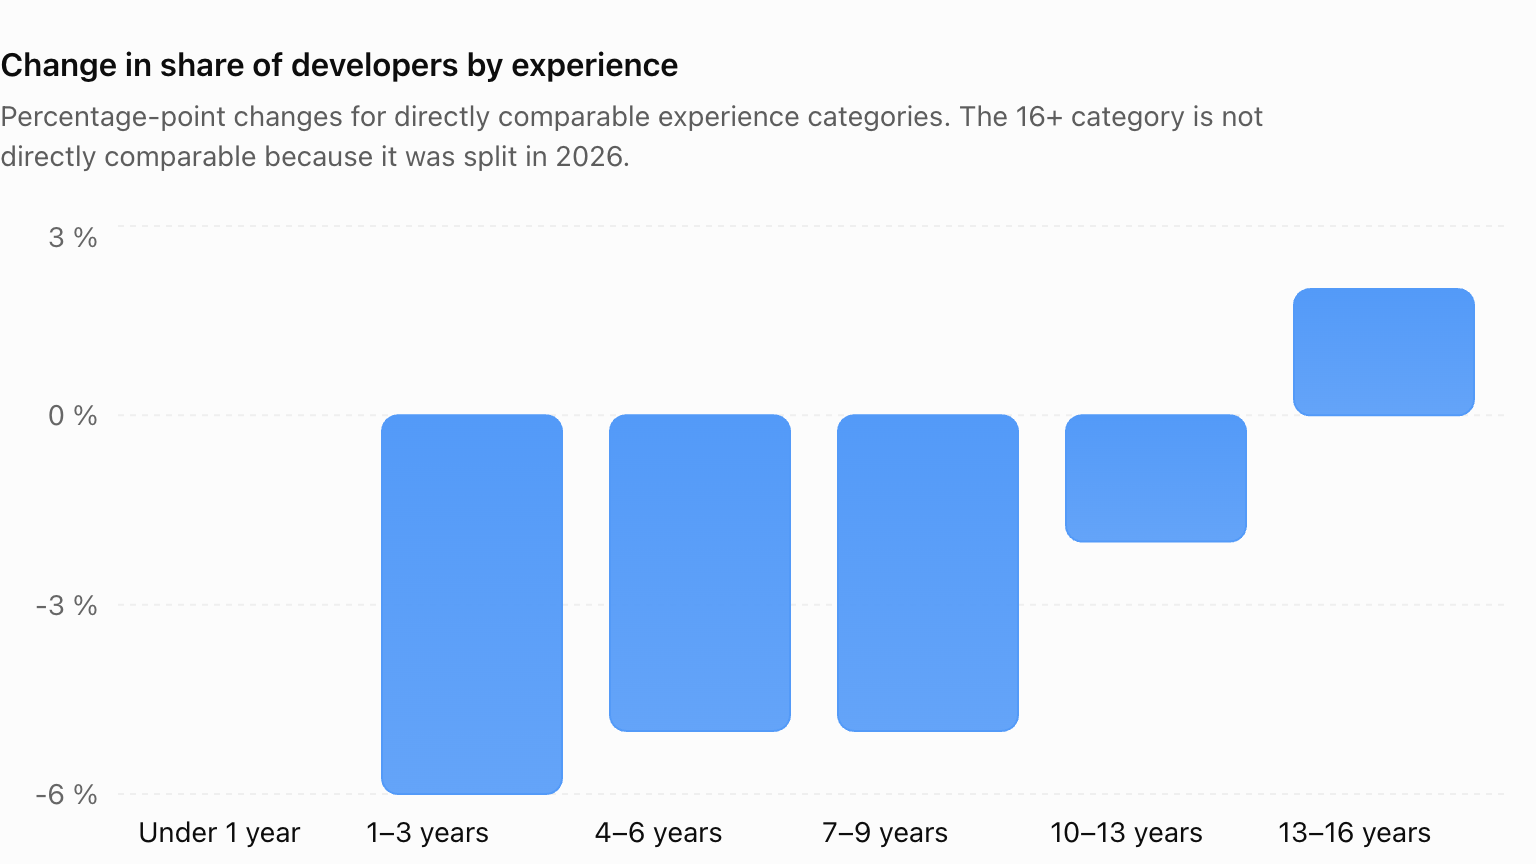
If we look at the change by experience cohort, the aging & dropping out problem is pretty clear. Perhaps the only good news is that Rails maintains a constant small trickle of new people trying the platform.
AI Adoption
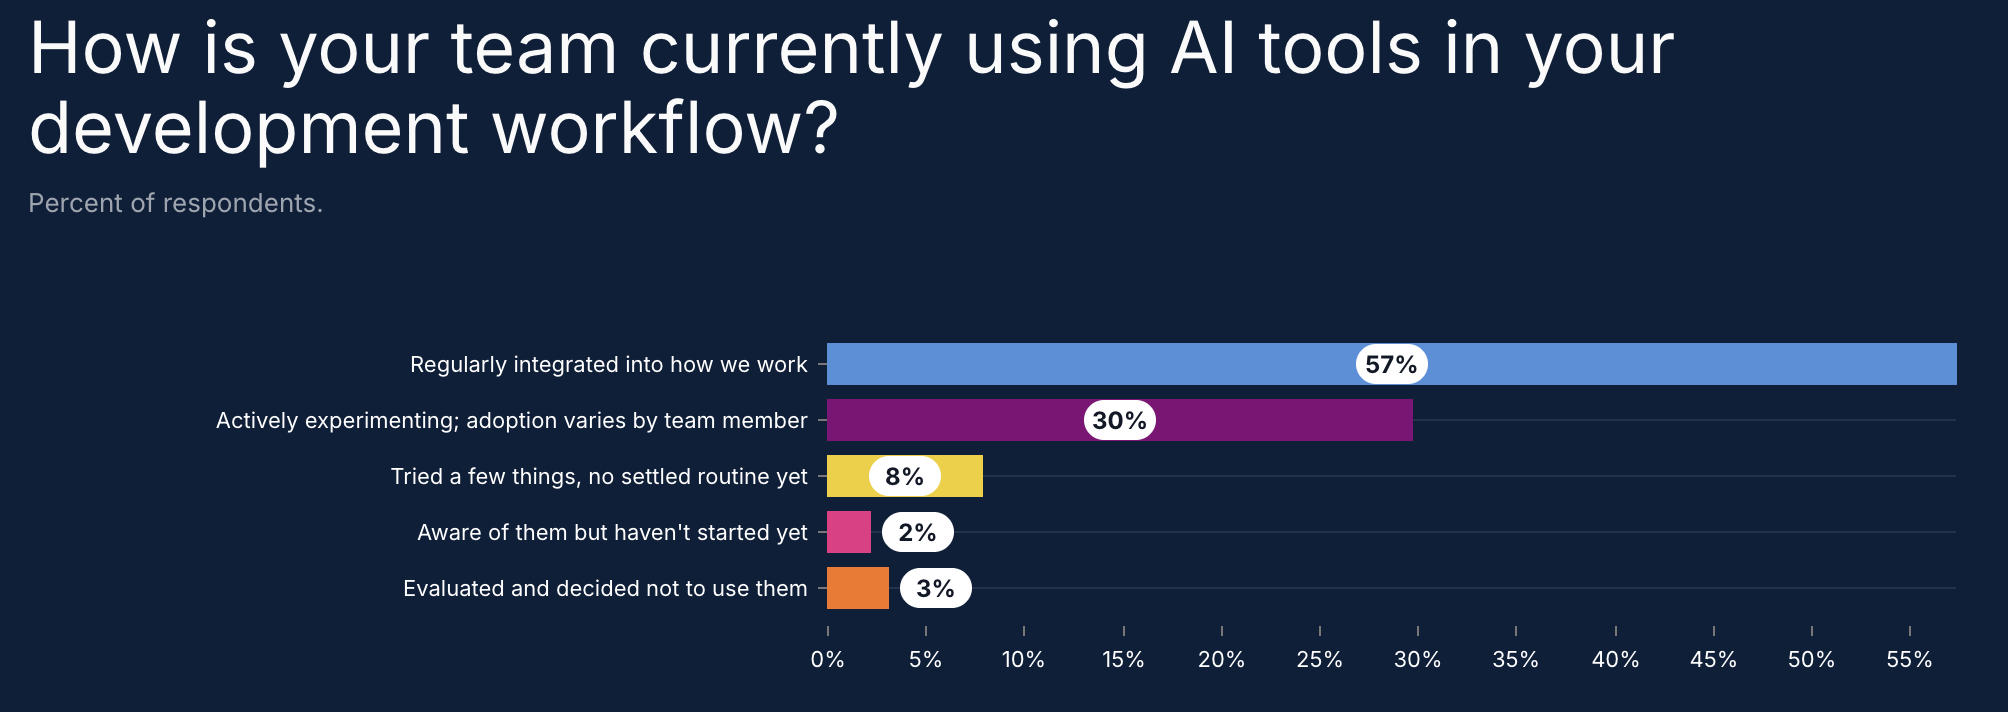
For those that remain, AI adoption is pretty much universal, with sentiment largely positive.
I suspect that AI tools are as good if not better at generating Ruby and Rails code over most other languages, simply because the community values of open source and test driven development has created an awesome training data set as its legacy.
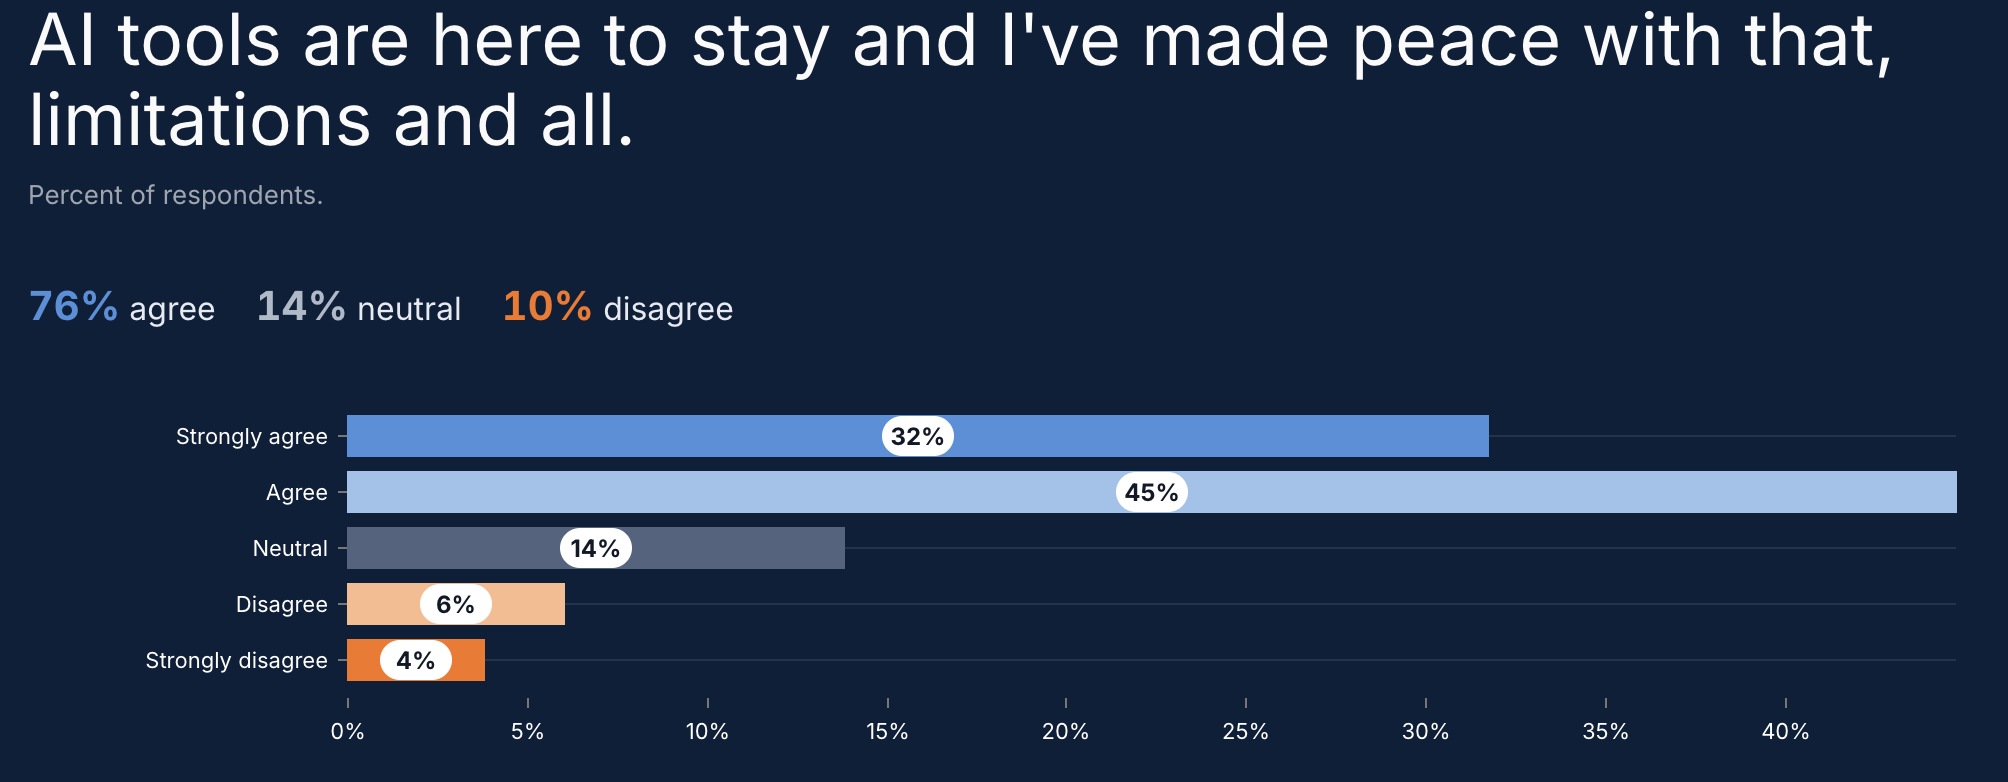
Fewer Juniors. More AI. A Tyranny of Seniors?
It makes one wonder about the future we are facing: a few aging seniors overseeing an army of AI agents?
The looming issues are obvious:
- We have a pipeline problem Where are the replacements for the seniors coming from when the current cohort shuffle off this mortal coil?
- We have an innovation dilemma AI tools are trained on existing technology, and are really good it writing code accordingly. This disincentivizes core innovation, as it degrades agent effectiveness. Coupled with the aging demographics, we get doubly-incentivised to just let the Rails platform stagnate.
This may work out in the short-term. As always, some heroic efforts of individuals will likely carry the community forward.
But are we eventually going to be dealing with an ossified platform, with no-one remaining with the skills or incentive to keep it alive?
The big question is of course what happens with AI. The most optimistic view is that we’ll soon get to something like AGI (at least within the domain of software development), such that:
- there is no longer the need for a skilled developer in the loop
- it is capable of significant platform innovation without skilled developer guidance
Maybe. Personally I do not believe the currently generation of transformer-based large language models will be able to achieve this before they hit fundamental brick-walls. It’s all riding on what comes next…
read more and comment..
LLM Limits: GPUs or Data?
Large Language Models (LLMs) are statistical inference machines that project from available data and training sets. When they stray beyond the data, they hallucinate. Which may be a good thing, depending upon your intent. But usually not. LLM advances in the past 10 years have largely been constrained by the capital and supply-chain wizardry required to put farms of GPUs on the job of training the latest model. But are we reaching the point where DATA becomes the strangling bottleneck, not GPUs?
The Bait And Switch
Remember the early days of AI hype, promising to cure cancer and solve climate change?
Well, … no. Things are a lot more prosaic these days.
In his 2026 presentation to the Royal Society, Professor Michael John Wooldridge explained how the LLM breakthroughs of the past 10-20 years really just boil down to the ability to apply scale (i.e. lots of GPUs and storage) to a simple and elegant idea - the transformer.
What was the training data that the model builders were using? Andrej Karpathy famously characterised model training as a lossy compression of the Internet.
While Common Crawl remains a good starting point for experiments, leading efforts such as OpenAI GPT-family models are trained on combinations of:
- Public web data
- Licensed data
- Human-created data
- Code repositories
- Books and reference materials
- User interactions
Which sounds great. All of human knowledge in a bottle!
But not quite.
I’ve noticed that people in tech, especially, over-estimate the completeness of the Internet. After-all, the early Internet cultivated an apparently self-evident truth that information wants to be free
.. as documented by Steven Levy in Hackers: Heroes of the Computer Revolution.
So how much information, and more importantly knowledge, is readily machine-reasonable? Some may be surprised that is is still a relatively small fraction, likely <5–10% of all recorded human knowledge.
If you include all tacit knowledge: far less than 1% is represented.
A quick thought-experiment may help:
Think of your last job, and the key activities you were occupied with to be successful day-to-day. How much of that was captured, written down, and stored somewhere?
For most people, even in very digitized roles, the answer is somewhere between “none” and “very little”. And that is how much data the AI has to work with.
Does it matter though?
A casual interaction with an LLM may appear satisfactory. That may be a low bar, as the roasting that Richard Dawkins got for his Claude Delusion illustrates.
My retrospectively-enlightening career is festooned with examples of good intentions boldly proceeding before an absence of data. To wit…
Skinny Data
Data, though rich an voluminous, does not contain the necessary detail
I recall conducting a machine-learning exploration on 12 years worth of customer support data. Multiple gigabytes of valuable digital dust.
It was successful to a degree: the model could predict resolution categorization with a high degree of confidence.
But it couldn’t determine exactly how to resolve a given case, because the actual technical steps and details were not recorded in the dataset.
So if you wanted to build an AI replacement for the support agent with this data, what you’d get would go something like this:
Customer: I seem to have problem X with these symptoms Y and Z. Can you help?
AI: Of course we can! Based on my training data I can confidently say that our resolution would be “Network Configuration”
Customer: er, ok? So what exactly should I do?
AI: Sorry, you are right, my instructions were not clear. To solve the problem, you just need to fix your Network Configuration.
As the basis for anything remotely useful or intelligent, it turned out that the data was pretty much useless.
The data-capture challenge was that much of the real action happened “off-screen”. If the support agent needed to swivel and ssh into a remote device … totally transparent. Or consult with a colleague … unrecorded. Or use an air-gapped device to do some queries .. unmonitored.
It’s almost as if 90% of the job did not leave a digital footprint.
Correct!
And that was for a technical job. Imagine how much of a non-technical job fails to leave the digital footprints that an AI requires. 98+%?
Key learning:
Most “jobs” do not leave a meaningful digital footprint. If you want to capture the details, you will need a specific data capture initiative.
Meta may have belatedly wizened up to this deficit in their datasets, before it was revealed that they would start capturing employee mouse movements, keystrokes for AI training data.
Shadow Data
The data is out there, but it can’t be accessed
I’ve noticed this is a particular problem with historical research, as an example.
If one is looking for specific information, such as aircraft tail codes and operations logs, or uniform details for specific information, the information may exist somewhere - but it is in a book on a shelf, in a museum, library, or archive, and definitely not part of the training data, or accessible by search.
AI responses on such topics will be lacking in the necessary detail, or worse, fictitious.
If one were to ask, for example, about the uniforms worn by the Japanese in Peleliu, we get:
- Olive-drab or khaki cotton tunic and trousers
- Often faded to light brown, tan, or greenish-grey from tropical exposure
- Many wore simplified tropical shirts instead of full tunics
- Puttees (cloth leg wraps) or canvas gaiters
- Split-toe tabi shoes or hobnailed ankle boots
i.e. generally correct, but specifically imprecise.
Not useful! There is a great deal of information that is either not generally accessible, yet to be digitized, or in a language not in the training set.
Data Black Hole
No-one thought to collect that data yet
Early in my career, I was involved in projects to improve predictive machine maintenance.
The problem was: the machines didn’t produce any data.
So the first step in most projects was to figure out what data you really needed, and how to collect it. It was usually a non-trivial exercise in itself; often the bulk of the dollars spent.
And these projects were successful, but for very bounded problems.
These days, people often assume the data is a given, or simply subject to a price for access being agreed.
But no. So much or the world remains inaccessible to machine-reasoning.
Key learning:
Do not underestimate the challenge of capturing “all the data”.
The Best Datasets
Hang on, I thought we were supposed to be curing cancer, solving climate change, or something equally important?
But no, we’re optimising software development instead!!!!
It is no surprise that “coding” is the domain within which AI agents got really good.
Coding presents the most complete and self-contained dataset, with much of the technical field available for AI training from books, blogs, and open source repositories such as LeetCode-Solutions, and an almost infinite selection of example TODO list implementations.
So we proclaim “job done”! … before remembering we were meant to be solving more important problems.
Are we selecting the best data to solve the most important problems, of finding the easiest problem that the most available data can solve?
Remember 2015, the year the world declared developer productivity as the most imminent threat to humanity?
Wait, no! It was water crises and interstate conflict.
Has AI helped solve those problems? No.
But At Least AI Can Code
Hmm, AI still falls short at just generating code.
In my experience, the biggest challenge in software engineering is “figuring out what people want/need”.
Call it requirements analysis, UX design, or just consulting - bringing clarity to the messy mix of inter-personal and business incentives was always the more critical (and challenging) part of project.
The part that AI is far from being able to master.
Where To From Here?
More Data
If we pursue the LLM paradigm, then clearly what we need is more data.
Current LLMs, no matter how good they appear to be, are working on datasets that represent less than 1% of all knowledge.
But all the easily accessible data has already been plundered.
QED: LLMs need a massive data collection exercise, like Meta’s MCI.
But surely this as an exponential race to the bottom? As fast as GPUs can process, we need even more data to ingest.
Unbounded by Data
Or perhaps LLMs are an evolutionary dead-end?
Ineffable Intelligence was founded by David Silver in November 2025 to chart an alternative path: focus on developing reinforcement learning algorithms that would have the ability to endlessly discover knowledge and skills, rather than the transformer approaches that are fundamentally bounded by the data they have available.
Translated, I believe this simply means:
- rather than just work on data we are given
- we will go collect data for ourselves
Presumably with suitably Black Mirror-esque data appendages and sensors to cross the machine-ecosystem boundary.
Composability
I’ve been increasingly drawn to the concept of job composability as a way of thinking about AI impacts on the workforce.
Task composability is a design principle where complex workloads are broken down into smaller, independent, and reusable “tasks” that can be easily combined or reconfigured to create new workflows.
Most AI pitches assume they can do the “whole job”. But real people know this is BS.
So the question becomes: can AI do a little bit of the job, and a human do the rest?
It depends on whether the task is composable or not.
A good example of a composable task could be content marketing: an AI can independently take care of Research & Data Gathering, while a human can take care of selecting appropriate sources and tailoring the pitch for the client.
Typical characteristics of non-decomposable tasks:
- Lack of Objective Truth: Tasks where the “correct” answer depends entirely on subjective human values. e.g. writing a sympathy card for a friend
- Tacit Knowledge: Skills that are learned through physical embodiment rather than data. e.g. how to master kigumi
- High-Stakes Accountability: Roles where a human must “own” the moral consequences of a decision. e.g. someone must be on the line for this forecast call!
Conclusion
So this is the rational middle-ground: LLMs are not worth the trillion dollar valuations, but they can be useful in the routine course of working a task.
I just don’t want to be the person stuck with that AI training bill, like the investors who paid for the Global Crossing bankruptcy and unwittingly ushered in the era of “effectively free” global communications!
read more and comment..
AISLE: The End of Zero-Days?
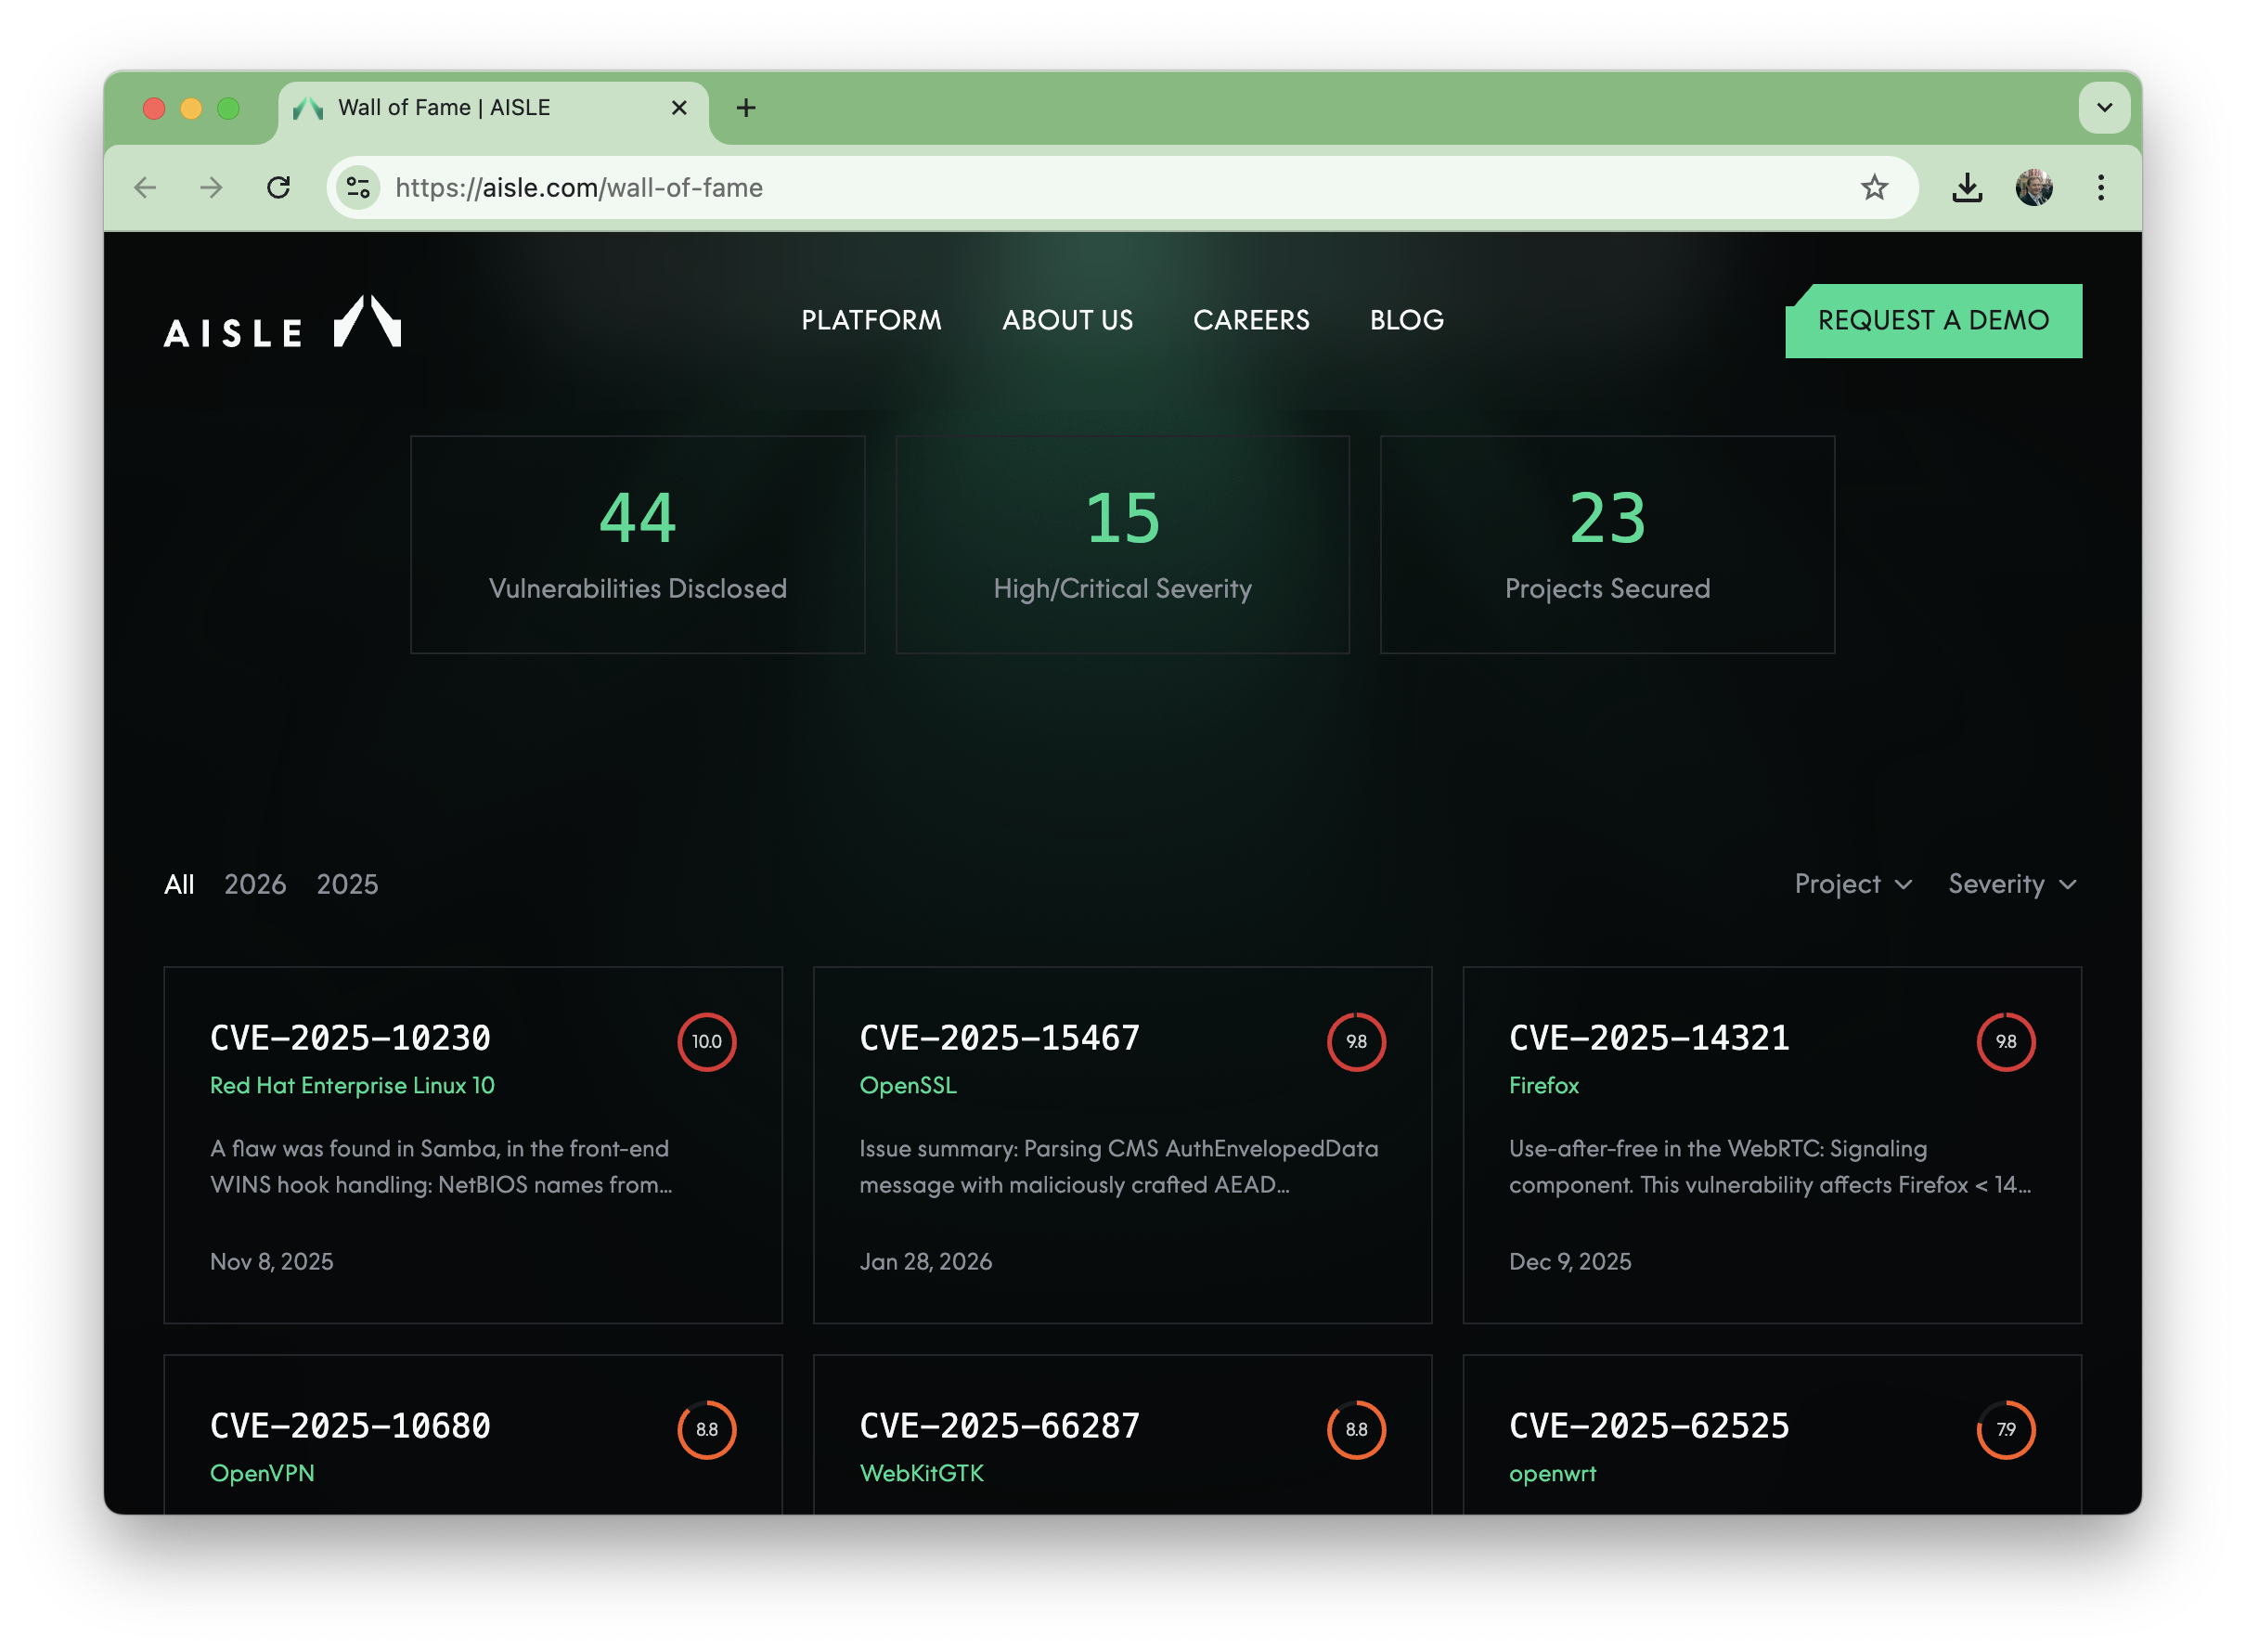
AISLE have been developing a complete AI workflow for deep cybersecurity discovery and remediation,
and if their Wall of Fame is any indicator of potential,
they may prove to be one of the most transformative companies to emerge from the AI bubble.
I must admit to being a little jaded. Where are all the AI startups delivering meaningful breakthroughs?
We were sold a vision of AI curing cancer, ending the climate crisis, and eliminating poverty.
Instead, much of the commercial narrative seems to have fixated on workforce reduction and generating a tidal wave of AI slop, along with a huge power bill.
So I wasn’t expecting to be impressed when I heard about AISLE on Security Now #1063.
But I was.
It’s 2026, and we still treat vulnerabilities as “Normal”
Since computing’s original sin of mixing code and data, security has been a cat-and-mouse game. We’ve made enormous advances in system and network security, yet we still accept one assumption as inevitable:
There is no such thing as bug-free code.
As developers, we follow secure coding practices. We run static analysis. We adopt DevSecOps pipelines. And still, vulnerabilities ship.
Our experience with AI coding tools such as Claude Code and GitHub Copilot is mixed. They fix some bugs, hallucinate others, chase red herrings, and lack a true closed-loop workflow for discovering and eliminating security flaws.
What is AISLE doing differently?
AISLE’s ambition is simple and radical: software released with zero known security vulnerabilities. Where software is assured by AISLE to be free from security vulnerabilities before it is released.
The company emerged from stealth in October 2025. In the absence of reliable cybersecurity benchmarks, they targeted live, heavily audited open-source projects including:
- OpenSSL
- curl
- Firefox
- Linux
- OpenVPN
The results have been remarkable:
- OpenSSL security patch of 2026-01-27 addressed 12 new zero-day vulnerabilities - all discovered and remediated by AISLE
- curl 8.18.0 released January 8, 2026, AISLE was responsible for 3 of the 6 CVEs
If accurate, that’s not incremental improvement. That’s industrialized vulnerability discovery and remediation.
AISLE appears to be succeeding not by building a better autocomplete engine, but by creating a full AI-driven workflow dedicated to one problem space.
Is “Zero Vulnerabilities” Realistic?
For many of us versed in the “old ways”, this sounds too good to be true! And to be sure, if software is free from security vulnerabilities, that is not the end of security issues.
Even perfect code doesn’t eliminate phishing or credential theft. Humans will always remain part of the attack surface.
But removing exploitable software flaws changes the economics of cybercrime dramatically. No zero-days means fewer catastrophic breaches.
Another AI Unicorn?
AISLE emerged from stealth backed by angel investors. No major institutional round or valuation has been disclosed yet.
But if their trajectory continues, they may become something rare: not the first AI unicorn, but possibly the first AI unicorn to actually do something significantly good for the world!
What Happens Next?
The obvious path is integration into CI/CD pipelines with a security assurance as a subscription service. One can request a demo, but I’ve not yet seen any pricing.
Longer term? Pure speculation, but I would not be surprised to see a rapid exit and acquisition. My bet would be Microsoft:
- to use internally:
- A world without Windows security patches, because there are no vulnerabilities to fix!
- to integrate with Microsoft-owned GitHub as a value-added service:
- A perfect pairing or upgrade to the existing Dependabot and Code Scanning services
- A must for enterprise clients, while ensuring the open-source supply chain that so many companies rely on is kept free from issues
If AISLE can assure software security before release, “reasonable industry practice” changes. Releasing vulnerable code may eventually be considered negligent under the law, with the old “no liability” boiler plate in license agreements challenged in court. Be prepared to defend why you are not using a service like AISLE!
References:
- aisle.com
- AI found 12 of 12 OpenSSL zero-days (while curl cancelled its bug bounty)
- Security Now Episode #1063
read more and comment..
AI in the Call Centre
AI is decimating call centres, but two can play at that game!
Inspired by true events😂
read more and comment..